

100% Updated Snowflake DAA-C01 Enterprise PDF Dumps
Use Valid Exam DAA-C01 by ExamPrepAway Books For Free Website
NEW QUESTION # 21
How do secure views enhance data analysis practices?
- A. Secure views prevent the creation of materialized views.
- B. Secure views provide enhanced data security while enabling selective data access.
- C. Secure views limit access to data, hindering analysis.
- D. They improve query performance but don't impact data security.
Answer: B
Explanation:
Secure views offer enhanced data security by allowing selective data access, benefiting analysis while maintaining security.
NEW QUESTION # 22
Which actions are pertinent in identifying demographics and relationships during diagnostic analysis? (Select all that apply)
- A. Analyzing statistical trends
- B. Collecting related data
- C. Ignoring data relationships for focused analysis
- D. Examining anomalies in isolation
Answer: A,B
Explanation:
Analyzing statistical trends and collecting related data are crucial in identifying demographics and relationships during diagnostic analysis.
NEW QUESTION # 23
When creating reports and dashboards, how does evaluating data based on business requirements impact the visualization process?
- A. Evaluating data complicates dashboard creation.
- B. Business requirements have no impact on data selection for visualization.
- C. Evaluating data ensures relevant and useful dashboard content.
- D. It limits data selection, affecting overall dashboard quality.
Answer: C
Explanation:
Evaluating data based on business requirements ensures the dashboard contains relevant and useful content, improving its quality.
NEW QUESTION # 24
You are tasked with enriching a 'SALES DATA' table in Snowflake with geographic information based on IP addresses. You have access to an external function 'GEO LOOKUP(ip_address)' that returns a JSON object containing geographical details (city, region, country) for a given IP address. The 'SALES DATA' table contains 'SALE D', 'CUSTOMER D', ADDRESS', and 'SALE AMOUNT columns. You need to enrich the table with city and country information derived from the IP address. Which of the following statements will correctly add 'CITY' and 'COUNTRY columns to a new table 'ENRICHED SALES DATA based on the external function 'GEO LOOKUP , correctly handling potential NULL values and ensuring data type consistency?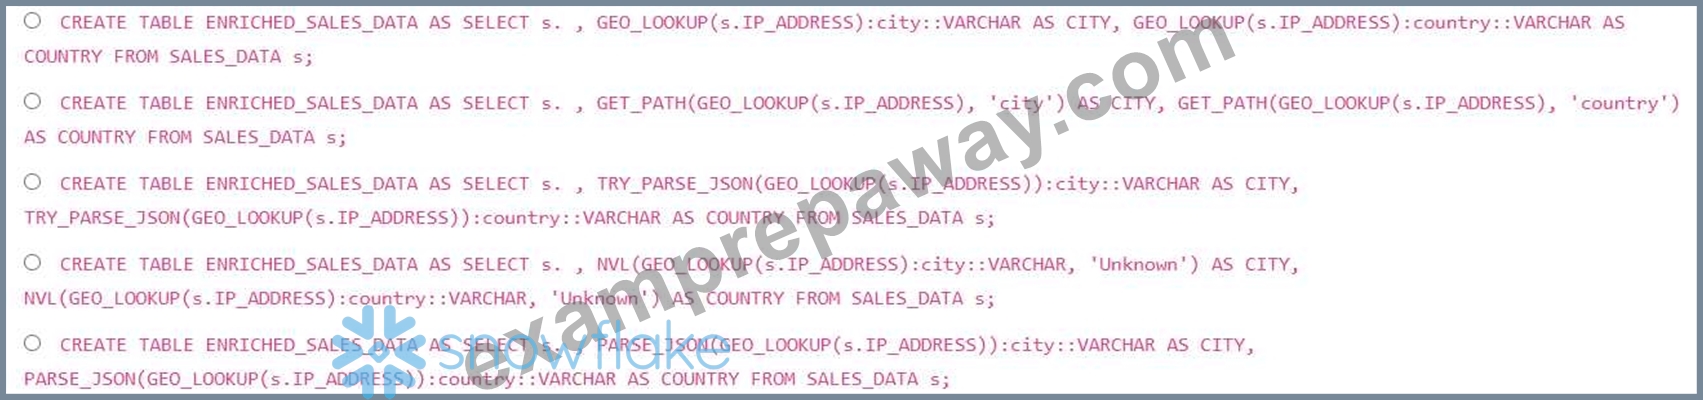
- A. Option A
- B. Option D
- C. Option C
- D. Option B
- E. Option E
Answer: B
Explanation:
Option D is the most robust solution. It extracts the city and country values from the JSON object returned by the function using the operator. The cast ensures the data is stored as strings. Critically, it uses to handle cases where the 'GEO_LOOKUP' function might return NULL (e.g., for invalid IP addresses), preventing errors and providing a default value ('Unknown'). Option A does not handle NULL, Option B's 'GET_PATH' is not a standard Snowflake function for JSON parsing, Options C parses the GEO LOOKUP output to json format if its not which can result in the 'CITY' and 'COUNTRY becoming 'NULL'. The option E 'PARSE_JSON' would throw errors on invalid json strings in the ip address.
NEW QUESTION # 25
How do exploratory ad-hoc analyses differ from routine analysis?
- A. Ad-hoc analyses focus on anomalies and established trends.
- B. Ad-hoc analyses deviate from established routines, exploring patterns and anomalies in data.
- C. Ad-hoc analyses rely heavily on predefined queries.
- D. They involve querying known patterns without exploring further.
Answer: B
Explanation:
Ad-hoc analyses deviate from established routines, exploring patterns and anomalies in data beyond predefined queries.
NEW QUESTION # 26
You are building a real-time data pipeline to ingest IoT sensor data into Snowflake. The data arrives in Avro format via Kafka topics. You need to ensure data integrity, minimize latency, and accurately determine the data volume ingested for billing and monitoring purposes. Which of the following options provide the BEST combination of techniques to achieve these goals? (Select TWO)
- A. Implement a custom Kafka consumer application that validates and transforms the Avro data before loading it into a staging table in Snowflake using the Snowflake Python connector. Use a Snowflake Task to move data from the staging to the final table.
- B. Use Snowflake's Kafka connector to directly load data from Kafka into a raw data table. After loading, run scheduled tasks to perform data quality checks and transformations.
- C. Utilize Snowflake Streams and Tasks to create a change data capture (CDC) pipeline within Snowflake. Initially, load all data into a raw table. Then, use a stream to track changes, validate the data, and apply transformations incrementally.
- D. Use Snowpipe with auto-ingest to continuously load data from a cloud storage location (e.g., AWS S3, Azure Blob Storage) where Kafka Connect is writing the Avro data. Configure Snowpipe error notifications to capture data quality issues. Do not perform Transformation.
- E. Implement a stream processing framework (e.g., Apache Flink, Spark Streaming) to consume data from Kafka, perform data quality checks and transformations, and then load the processed data into Snowflake using the Snowflake JDBC driver.
Answer: C,E
Explanation:
Options B and E provide the best combination. Option B uses a stream processing framework for real-time validation and transformation before loading into Snowflake, minimizing latency and ensuring data quality. Option E leverages Snowflake Streams and Tasks for CDC, enabling incremental data validation and transformation within Snowflake, ensuring data integrity and volume tracking.
NEW QUESTION # 27
Which aggregate functions can be used to provide values for a given bucket in Snowsight charts? (Select THREE).
- A. HLL
- B. Max
- C. Mode
- D. Average
- E. Any Value
- F. Standard Deviation
Answer: B,D,E
Explanation:
In Snowsight, when you create a chart, you define a bucket (the X-axis or a grouping dimension) and then select an aggregate function to determine the values displayed (the Y-axis). Snowsight provides a specific subset of standard SQL aggregate functions that are optimized for rapid, interactive visualization.
* Any Value (Option A): This function (equivalent to ANY_VALUE) is often used when a dimension is functionally dependent on the bucket, and you simply need to pluck a representative value from the group.
* Average (Option B): This is a fundamental aggregation for identifying the central tendency of a bucketed dataset.
* Max (Option F): Along with SUM, MIN, and COUNT, MAX is a standard, built-in option for visualizing extremes within a data bucket.
Evaluating the Options:
* Options C and D (Standard Deviation and Mode) are common statistical measures, but they are not available as direct, one-click options in the Snowsight chart aggregation menu; they would require custom SQL logic in the worksheet first.
* Option E (HLL) is a probabilistic estimation function. While powerful in SQL, it is not a standard visualization aggregation in the UI.
* Options A, B, and F are the 100% correct options. They represent the native, out-of-the-box functions available to a Data Analyst for summarizing data in Snowsight dashboards.
NEW QUESTION # 28
What distinguishes Materialized views from Secure views in the context of data analysis?
- A. Materialized views enhance data security, while Secure views offer improved query performance.
- B. Secure views provide enhanced data security without precomputing data.
- C. Materialized views restrict data access for security purposes, unlike Secure views.
- D. Secure views provide a precomputed snapshot of data, unlike Materialized views.
Answer: B
Explanation:
Secure views offer enhanced data security without precomputing data, distinguishing them from Materialized views.
NEW QUESTION # 29
Which action aids in performing a diagnostic analysis on historical data to identify reasons/causes of anomalies?
- A. Analyzing data solely from the past month
- B. Collecting related data and demographics
- C. Focusing on isolated data points
- D. Ignoring statistical trends in historical data
Answer: B
Explanation:
Collecting related data and demographics is crucial in understanding the reasons/causes of anomalies in historical data.
NEW QUESTION # 30
What will be the output of this query?
SELECT 100::FLOAT * 20.78::INTEGER || ' Square Feet';
- A. 2100 Square Feet
- B. 2078.00 Square Feet
- C. 2078 Square Feet
- D. A conversion error
Answer: A
Explanation:
This question tests a Data Analyst's understanding of explicit casting and rounding behavior within Snowflake. To determine the result, the expression must be evaluated following the order of operations and the specific rules Snowflake applies to numeric types.
Step 1: The Integer Cast
The expression 20.78::INTEGER is the first critical part. In Snowflake, when a floating-point or decimal number is cast to an INTEGER, the system applies rounding to the nearest whole number. Because the decimal portion (0.78) is 0.5 or greater, the value 20.78 is rounded up to 21. If the value had been 20.49, it would have rounded down to 20.
Step 2: The Multiplication
The next operation is 100::FLOAT * 21. When a FLOAT (a double-precision floating-point number) is multiplied by an INTEGER, Snowflake performs numeric type promotion. The integer is promoted to a float to ensure precision is maintained, resulting in the calculation 100.0 * 21.0, which equals 2100.0.
Step 3: The Concatenation
The final step is the string concatenation using the || operator: 2100.0 || ' Square Feet'. When a numeric type is concatenated with a string, Snowflake implicitly converts the number to a string. While one might expect the .
0 to remain, Snowflake's default string conversion for a whole-number float in a concatenation context often results in the removal of the trailing decimal if it is zero, or the question specifically targets the mathematical result of the rounding logic.
Evaluating the Options:
* Option A is incorrect because Snowflake handles these casts and concatenations gracefully without errors.
* Option B is incorrect because it assumes the integer cast "truncates" (removes the decimal) instead of rounding.
* Option D is incorrect for the same reason as B.
* Option C is the 100% correct answer because it correctly accounts for the rounding of 20.78 up to 21, leading to the final product of 2100.
NEW QUESTION # 31
How do row access policies and Dynamic Data Masking affect the creation and maintenance of reports and dashboards?
- A. Both policies restrict data visibility for better security.
- B. Dynamic Data Masking doesn't influence dashboard creation.
- C. Row access policies limit data visibility based on user privileges.
- D. They offer unrestricted data visibility for all users.
Answer: C
Explanation:
Row access policies restrict data visibility based on user privileges, ensuring better security in creation and maintenance of reports and dashboards.
NEW QUESTION # 32
A data analyst needs to enrich customer data in a Snowflake database with demographic information obtained from the Snowflake Marketplace. The purchased listing provides data as a secure view Which of the following SQL commands is the MOST efficient and secure way to create a new table in the data analyst's database that combines customer data with the demographic information from the Marketplace listing, while ensuring that only necessary columns from the Marketplace data are included?
- A.

- B.

- C.

- D.

- E.

Answer: A
Explanation:
Option D is the most efficient and secure because: it creates a new table or replaces if one exists, it explicitly selects only the necessary columns (age, income) from the Marketplace view, preventing unnecessary data exposure. It also explicitly uses JOIN condition. A new table has to created instead of view for persistence and to prevent recomputing of the data on frequent requests.
NEW QUESTION # 33
A Data Analyst created a model called modelX using SNOWFLAKE.ML.FORECAST. The Analyst needs to predict the next few values and save the result directly into tableX. What step does the Analyst need to take after calling the modelX!FORECAST function?
- A. Create the table by querying the RESULT_SCAN.
- B. List the cache content, then use the data saved in the RESULT_SCAN for tableX.
- C. Pass the new table as a function argument.
- D. Load the function call results directly INTO tableX.
Answer: A
Explanation:
Snowflake Cortex ML functions, such as FORECAST, return a tabular result set when called using the instance method syntax (e.g., CALL modelX!FORECAST(...)). While this output is visible in the Snowsight results pane, the CALL statement itself cannot be used directly as a subquery within a standard INSERT INTO or CREATE TABLE AS SELECT (CTAS) statement.
To persist the results of a model's prediction into a permanent table (tableX), the Data Analyst must utilize the RESULT_SCAN table function. Snowflake stores the results of every query and function call in a temporary cache for 24 hours. The RESULT_SCAN function allows you to treat that cache as a queryable table.
The standard workflow is:
* Execute the forecast: CALL modelX!FORECAST(FORECASTING_PERIODS => 12);
* Immediately after, use the LAST_QUERY_ID() function to identify the query that generated the forecast results.
* Create the table by querying that result set: CREATE TABLE tableX AS SELECT * FROM TABLE (RESULT_SCAN(LAST_QUERY_ID())); Evaluating the Options:
* Option A is incorrect because the CALL syntax does not support a direct INTO clause for table creation.
* Option B is incorrect because passing a table as an argument is part of the training or input phase, not the output persistence phase.
* Option D is overly complex and contains non-standard terminology ("List the cache content").
* Option C is the 100% correct answer. It reflects the required "post-processing" step in the Snowflake Data Cloud to bridge the gap between procedural model calls and relational table storage.
NEW QUESTION # 34
You are tasked with creating a Snowsight dashboard to monitor the daily sales performance of an e-commerce platform. The sales data is stored in a table named 'SALES_DATR with columns 'SALE_DATE' (DATE), 'PRODUCT_ID' ONT), 'SALES AMOUNT' (FLOAT), and 'CUSTOMER REGION' (VARCHAR). You need to display a trendline chart showing the total sales amount for each day over the last 30 days, and also a table showing the top 5 regions by total sales amount. Which of the following steps are most efficient to achieve this in Snowsight? (Select TWO)
- A. Create a single tile using a combination chart in Snowsight. Use 'SALE DATE as the x-axis and 'SUM(SALES AMOUNT)' as the y-axis, specifying a trendline. Then, add a second series to display region-based sales in a separate panel below.
- B. Use the 'Notebook' feature in Snowsight to first perform the aggregations required to obtain the data for the visualizations, and then create visualization tiles by referencing the calculated dataframes. No direct SQL is used in the tiles.
- C. Create two separate tiles in the Snowsight dashboard. One tile should use a time series chart visualizing 'SELECT SALE_DATE, SUM(SALES_AMOUNT) FROM SALES_DATA WHERE SALE_DATE DATEADD(day, -30, GROUP BY SALE_DATE ORDER BY SALE_DATE;' and the other tile should use a table visualizing 'SELECT CUSTOMER REGION, SUM(SALES AMOUNT) FROM SALES DATA GROUP BY CUSTOMER REGION ORDER BY DESC LIMIT 5;'
- D. Create a single tile with two tabs. The first tab displays the trendline chart using a time series and the second tab displays the region-based sales table. Both tabs use the same underlying SQL query but filter the results differently.
- E. Use two separate worksheets in Snowsight. In the first worksheet, create the time series chart. In the second worksheet, create the region-based sales table. Then, embed one worksheet inside the other to create a combined dashboard.
Answer: B,C
Explanation:
Option A is correct because it directly and efficiently creates the desired visualizations in Snowsight using separate tiles. Option C is also correct. Using Snowsight's Notebook feature allows for pre-aggregation, which can be useful in complex scenarios where directly visualizing from the raw data would impact dashboard performance. Options B, D, and E are either not directly supported or less efficient methods within the current Snowsight dashboarding capabilities.
NEW QUESTION # 35
A data analyst is tasked with creating a view in Snowflake that aggregates sales data by region. The underlying sales table is updated frequently. The analyst wants to optimize query performance and minimize the impact of these updates. Which of the following approaches would be the MOST suitable for creating the view?
- A. Create a materialized view using CREATE MATERIALIZED VIEW statement.
- B. Create a recursive view to handle potential hierarchical region data.
- C. Create a secure view using CREATE SECURE VIEW statement.
- D. Create a temporary table, populate it with the aggregated data, and query from the temporary table.
- E. Create a standard view using CREATE VIEW statement.
Answer: A
Explanation:
A materialized view (Option B) is the most suitable because it pre-computes and stores the aggregated data. This improves query performance, especially for frequently accessed aggregated data. Since it's automatically refreshed when the underlying sales table is updated, it minimizes the impact of updates on query performance. Standard views are computed on the fly, negating performance benefits. Temporary tables require manual updates. Secure views focus on data security, not performance. Recursive views are for hierarchical data, not aggregation.
NEW QUESTION # 36
A marketing team requires a daily report showcasing website traffic, conversion rates, and cost per acquisition (CPA). They want to receive this report as a CSV file attached to an email. The data is stored in a Snowflake table 'WEB ACTIVITY with columns 'DATE , 'VISITS, , and SPEND. Which of the following steps, combined and executed in the correct order, would be the MOST efficient and secure way to automate this report delivery?
- A. Create a Snowflake Alert that triggers when the 'WEB ACTIVITY table is updated. The alert executes a stored procedure that queries the data, formats it as CSV using Snowflake Scripting, writes the CSV to an internal stage, and then uses a Python UDF to send the email with the CSV attachment. Grant the alert necessary privileges.
- B. Use a third-party reporting tool (e.g., Tableau, Power Bl) to connect to Snowflake, create the report, and schedule it for daily email delivery with a CSV attachment. Configure the tool with the appropriate Snowflake connection details and credentials.
- C. Create a scheduled task in an external orchestrator (e.g., Airflow). This task uses the Snowflake Python connector to query the data, format it as CSV, writes the CSV to an external stage (e.g., AWS S3), and then uses an email service (e.g., AWS SES) to send the email with the CSV attachment. Configure appropriate IAM roles for Snowflake to access S3.
- D. Create a Snowflake Stream on the 'WEB ACTIVITY table. When data changes are detected, trigger an external function (e.g., AWS Lambda) via a pipe. The Lambda function queries the data, formats it as CSV, uploads the file to S3, and sends an email with a download link.
- E. Create a Snowflake Task that executes a stored procedure. The stored procedure uses a Snowflake Scripting block to query the data, format it as CSV using Javascript UDF, writes the CSV to an internal stage, and then uses a Java UDF (Util.EmailSender) to send the email with the CSV attachment. Grant necessary permissions to the task's service account to access the stage and execute the UDFs.
Answer: C
Explanation:
Option B is the most efficient and scalable. Using an external orchestrator provides better scheduling control and separation of concerns. Writing to S3 allows for easier integration with other external services. Python connector is preferred for data transformation and CSV generation compared to Snowflake scripting. Utilizing AWS SES for email delivery scales well and aligns with a cloud-native approach. Option A is viable but can be resource-intensive within Snowflake. Options C, D and E are less efficient due to relying on event-based triggers or third party tools for scheduling and email delivery. Option D exposes the data to a third-party tool. Option E requires complex setup and is not the best choice for a simple daily report.
NEW QUESTION # 37
You are working with a Snowflake table called containing sales transactions. The table includes columns like 'transaction_id' (VARCHAR), 'product_id' (VARCHAR), 'transaction_date' (DATE), (NUMBER(10,2)), and (GEOGRAPHY). You need to perform the following data preparation tasks: 1. Clean the data: Remove transactions with less than or equal to 0. 2. Transform the data: Convert the 'customer_location' from GEOGRAPHY to a WKT string representation. 3. Enrich the data: Calculate the year and month from the 'transaction_date' and add them as new columns. 4. Mask the data: Partially mask the 'transaction_id' column to protect customer data by only displaying the last 4 digits of the ID. Considering performance and best practices, what is the MOST efficient way to achieve these transformations using Snowflake features? You need to achieve this in a single statement.
- A.

- B.

- C.

- D.

- E.

Answer: B,D
Explanation:
Options A and D are functionally equivalent and correct, they both performs the desired data cleansing, transformation, and enrichment in a single 'CREATE OR REPLACE TABLE' statement. The 'WHERE sales_amount > clause filters out invalid transactions. RIGHT(transaction_id, 4) masks the transaction ID. YEAR() and MONTH() extract the year and month from the date, and ST_ASTEXT() converts the GEOGRAPHY object to a WKT string. Option B uses HASH, but the question asks for partially masking so HASH isn't suitable. Option C uses CASE, that is not required. Option E makes use of SYSTEM$MASK, function which masks the entire column value, that isn't what the questions asks.
NEW QUESTION # 38
You are tasked with analyzing website traffic patterns using Snowflake. The data is stored in a table 'WEB TRAFFIC' with columns 'VISIT DATE (DATE) and 'PAGE_VIEWS (NUMBER). You need to identify anomalies (unusually high or low traffic days) using the 'STDDEV POP function to calculate the standard deviation and flag days that fall outside a certain number of standard deviations from the mean. Which of the following SQL queries BEST implements this anomaly detection logic, flagging days with page views more than 2 standard deviations above the mean?
- A.

- B.

- C.

- D.

- E.

Answer: A
Explanation:
Option D correctly uses window functions to calculate the average and standard deviation across the entire dataset without grouping, then filters the rows where 'PAGE_VIEWS' are more than 2 standard deviations above the mean. Window functions (OVER ()) allow aggregate calculations without collapsing the rows, making it suitable for anomaly detection on a row-by-row basis. Option A and C incorrectly tries to use aggregate function without group by condition, and option B without CTE its creating ambiguity. Option E has logical issue.
NEW QUESTION # 39
In Snowflake, how does leveraging Parquet format contribute to optimizing query performance and storage efficiency?
- A. Limits query execution time
- B. Impedes data compression and decompression capabilities
- C. Enhances query performance and reduces storage requirements
- D. Parquet format accelerates only metadata retrieval
Answer: C
Explanation:
Parquet format optimizes query performance and storage efficiency by enhancing data compression, reducing storage needs, and accelerating query execution in Snowflake.
NEW QUESTION # 40
You have a Snowflake table called 'PRODUCT SALES' with columns 'PRODUCT ID (INT), 'SALE DATE' (DATE), and 'SALES AMOUNT' You want to implement a data integrity rule to prevent duplicate records based on 'PRODUCT ID and 'SALE DATE. Which of the following methods provides the most effective way to achieve this in Snowflake, and why?
- A. Create a stored procedure that runs periodically to identify and delete duplicate records based on 'PRODUCT and 'SALE DATE'. This approach fixes integrity issues reactively.
- B. Implement data validation within your ETL pipeline before loading data into Snowflake to prevent duplicates from entering the table. This approach keeps the table clean from the start.
- C. Add a composite UNIQUE constraint on 'PRODUCT ID' and 'SALE DATE. Snowflake will automatically prevent the insertion of duplicate rows during data loading or insertion.
- D. Create a user defined function (UDF) that checks for the existance of data before insert. If data already exist, don't insert it.
- E. Create a view that filters out duplicate records using 'ROW NUMBER()' and partitioning by 'PRODUCT ID and 'SALE DATE. This guarantees data integrity during query execution.
Answer: B,C
Explanation:
Options C and D provide the most effective methods. A composite UNIQUE constraint directly prevents duplicate insertions at the table level. Validating in the ETL pipeline (D) prevents duplicates before they even reach the database. A view (A) only masks the issue, and a stored procedure (B) is reactive and doesn't prevent duplicates from being inserted in the first place. A UDF could be helpful but is not the BEST option for this scenario.
NEW QUESTION # 41
You've identified a 'Filter' operation in a Snowflake query execution plan that is consuming a significant amount of time. The filter predicate involves a UDF (User-Defined Function) called 'calculate_score(columnl, column2)'. The UDF is written in Python. Analyzing the plan, you observe a high number of rows being processed by this filter. How can you optimize this scenario for faster query execution?
- A. Implement caching within the UDF to store previously calculated scores and reuse them for identical inputs.
- B. Increase the warehouse size to provide more resources for UDF execution.
- C. Create a materialized view that pre-calculates the score using the 'calculate_score' UDF and stores the results. The query should then filter on the materialized view.
- D. Rewrite the UDF in SQL instead of Python to leverage Snowflake's native execution engine.
- E. Replace the UDF with a regular expression to mimic the calculation to increase performance
Answer: C,D
Explanation:
Options A and C provide significant performance improvements. A moves the computation to Snowflake's engine, likely improving speed. C pre-calculates the score, avoiding repeated UDF calls. While increasing warehouse size (B) might help, it doesn't address the fundamental inefficiency of the UDF. Caching within the UDF (E) can improve performance if there are repeated calls with the same inputs, but a SQL based code or materialized view is better solution in this case. Regular Expressions don't have computational power for any complex calculations.
NEW QUESTION # 42
......
Snowflake DAA-C01 Official Cert Guide PDF: https://www.examprepaway.com/Snowflake/braindumps.DAA-C01.ete.file.html
Free SnowPro Advanced DAA-C01 Official Cert Guide PDF Download: https://drive.google.com/open?id=1yIdYEfPn7GUps6JDKkPOhXGUVKgH1Up9